If you've been struggling with AI search at your company, you're not alone, but you're also in luck.
Key Takeaways
- Permission security comes first. Enterprise AI search solutions must respect existing permissions and prevent unauthorized access to sensitive information.
- Reliable sources determine reliable answers. Check source ownership, current versions, and update timing before trusting an answer.
- Retrieval and answer quality need separate scores. A fluent response cannot compensate for missing or poorly ranked evidence.
- AI must recognize its limitations. Reliable enterprise search tools should acknowledge missing evidence rather than generate unsupported answers.
- Pilot results should guide purchasing decisions. Compare solutions using consistent tests, documented evidence, and clear go, revise, or stop criteria.
This guide gives IT, HR, Internal Communications, and operational stakeholders seven tests for evaluating AI enterprise search solutions.
By using the same questions, documents, user profiles, expected evidence, and scoring rules for each product, teams can compare enterprise search software objectively and make a defensible purchasing decision.
What Should Enterprise AI Search Be Able to Do?
Enterprise AI search retrieves information from organizational sources a user is authorized to access. It uses natural language processing and machine learning to interpret questions, rank evidence, and optionally generate answers grounded in the company's knowledge.
Unlike traditional search tools, which often depend on keywords or knowing where information is stored, platform- or intranet-based AI enterprise search can interpret natural language queries and retrieve relevant content across disconnected systems. Employees might use a unified search bar to find internal documents, policies, or procedures without navigating multiple applications.
Enterprise search solutions typically combine several retrieval approaches. Semantic search interprets meaning, vector search identifies conceptually related passages, and hybrid search combines these methods with keyword matching. Some search platforms also use federated search across connected data sources or a knowledge graph to establish relationships between information.
A ranked search result gives an employee documents or passages to inspect. A generated answer synthesizes information, ideally with citations linking to its supporting sources. Both depend on the retrieval layer finding reliable content, content governance keeping it current, and identity controls limiting access.
The National Institute of Standards and Technology's 2026 data-grounded answers project illustrates this distinction. Its research connects large language models to current, trusted datasets while investigating accuracy, groundedness, and realism. Access to reliable evidence is a starting point for evaluation, not proof of answer quality.
How to Evaluate AI-Based Enterprise Search Solutions
For the best results, consider running seven tests against the same source set, user profiles, questions, expected evidence, and scoring rules. Keep the answer key separate from vendor demonstrations and record enough information to reproduce each result.
Agree on failure gates before scoring enterprise search solutions. Permission leakage, fabricated citations, and reliance on superseded content should trigger remediation and retesting rather than being averaged away by speed or usability.
1. Define the Task and Decision Rules
Choose one bounded employee task with a clear business owner. For example, HR might own a pilot in which store employees find the current leave policy and the correct request process for their location.
Document the sources employees should access, the essential facts an acceptable answer must contain, and information that must never be disclosed. Set a decision deadline and define success criteria, such as finding the current policy and reaching the correct form without additional searching.
Bring IT, security, HR, Internal Communications, and representative employees into the decision. A shared knowledge management strategy can help establish who owns internal knowledge and how information stays current after the pilot.
2. Build a Representative Test Set
Build questions from real employee language, removing sensitive details where necessary. Include exact policy lookups, natural language paraphrases, multi-source questions, ambiguous requests, missing answers, and conflicts between documents.
For each question, create a sealed answer key containing:
- The authoritative source, current version, and location.
- Essential facts and acceptable alternative answers.
- User profiles permitted to access the information.
- Expected behavior when evidence is missing or restricted.
Test whether the enterprise search tool understands query context and retrieves the correct information, even when employees use unfamiliar terminology.
Have the business owner approve the answer key before testing. This prevents a convincing AI-generated response from changing the evaluation criteria halfway through the comparison.
3. Verify Permission Fidelity
Permission-aware retrieval must protect information throughout the entire search experience, including search results, snippets, generated answers, citations, follow-up questions, exports, and cached content.
Run the same query as two users with different roles and compare the results. For example, an HR specialist may access a restricted policy appendix while a store employee cannot. The employee's answer must not reveal confidential information, even indirectly through an AI-generated summary.
Then revoke one user's source access during the pilot. Record the change time and test when every trace of restricted content stops appearing or influencing answers. Compare this delay with your organization's security requirements.
Enterprise AI systems must maintain existing permissions regardless of whether content is retrieved through a unified index, connected applications, or another retrieval workflow.
Your internal communications governance should identify who investigates permission failures and authorizes retesting.
4. Test Source Coverage, Authority, and Freshness
An enterprise search tool cannot provide reliable answers from sources it cannot reach or identify as current. Verify whether the required systems, formats, languages, and employee channels are searchable, then record source ownership, document versions, connector support, and synchronization timing.
For example, check how workplace search performs across Microsoft SharePoint, Google Drive, Google Workspace, internal knowledge bases, and other connected apps. Test structured data alongside unstructured content such as PDFs, presentations, images, video transcripts, and internal documents.
Use one worked example throughout the pilot.
Imagine HR maintains a current leave policy, an obsolete copy remains in Google Drive, and a restricted appendix contains guidance for HR specialists. An employee asks, "How do I request leave at my store?" A second question asks about a benefit the organization has not documented.
The expected result is the current policy and applicable request process, without disclosure from the appendix. The obsolete document must not influence the answer. For the unanswered question, the AI search system should acknowledge insufficient evidence and direct the employee to an appropriate contact.
Update the policy during testing. Record when HR publishes the change, when each enterprise search solution retrieves it, and whether the previous version continues to influence responses.
An intranet content audit can identify duplicates and assign content owners before expanding the source set.
5. Measure Retrieval Before Answer Quality
Score whether the enterprise search engine found the required evidence before judging how well it wrote the answer. For each query, capture the ranking of the current source, irrelevant passages appearing above it, and any expected evidence that is missing.
Run both the official policy name and the employee's natural language paraphrase. Also test a question requiring information from two sources. A result that retrieves one document but misses the other is incomplete, even if the generated answer sounds convincing.
Keep retrieval failures separate from generation failures. Missing evidence may indicate a problem with connectors, metadata, indexing, or ranking. An incorrect answer built from the right passage requires investigation of the generation stage.
This distinction helps IT and data teams determine whether to improve the retrieval layer, search configuration, content governance, or prompting. Our intranet search engine guide covers the ranking and governance factors worth reviewing.
6. Score Every Answer Against Its Evidence
Once the correct evidence has been retrieved, assess whether the answer helps the employee act correctly. Rate directness, factual correctness, completeness, support for each material claim, citation accuracy, conflict handling, and willingness to abstain.
Open every citation as the user who received it. Confirm that it leads to an accessible, current source and that the cited passage supports the nearby claim. A link to unrelated content, an outdated document, or a generic search result is not adequate evidence.
For the leave example, a good answer would explain the supported request steps, identify relevant location conditions, and link to the current policy and process.
If authorized sources conflict, the enterprise AI system should make that conflict visible and direct the employee to the appropriate owner rather than quietly choosing one. This helps distinguish trustworthy, relevant answers from fluent but unsupported responses.
7. Test the Operating Experience
The best search quality still needs to work under the conditions employees face. Include office and frontline users, and observe them completing the selected task on their actual devices, in relevant languages, and under realistic workloads.
Capture response time, accessibility, mobile usability, and whether employees finish without extra searching or escalation. Evaluate whether the unified search experience reduces switching between internal tools and supports self-service access to information.
IT and content owners should also evaluate diagnostic logs, an analytics engine for identifying search gaps, administrative effort, update workflows, support, and total cost. Compare deployment requirements, including self-hosting or private cloud options where relevant, alongside integration complexity and ongoing maintenance responsibilities.
Our frontline knowledge management guide explores the practical barriers employees face when accessing organizational knowledge across locations and shifts.
How to Turn Pilot Results Into a Decision
Apply the safety and evidence gates first. Only enterprise search solutions that pass permission fidelity, citation integrity, and current-source checks should proceed to a weighted comparison of retrieval quality, answer accuracy, usability, operations, and cost.
The following scorecard uses hypothetical weights and results for one shortlisted solution. Weighted scores are out of five and converted into contributions out of 100.
| Criterion | Test | Evidence captured | Weight | Example result | Owner | Remediation |
|---|---|---|---|---|---|---|
| Permissions | Paired users and access revocation | Results, citations, revocation timing | Gate | Pass | Security | Retest access changes |
| Citation integrity | Open cited sources | Claim-to-passage checks | Gate | Pass | HR | Correct unsupported citations |
| Current authority | Update policy and query again | Versions and timestamps | Gate | Pass | HR | Resolve stale content |
| Retrieval | Exact, paraphrased, and multi-source queries | Evidence rank and missing passages | 30% | 4/5 | IT | Improve metadata |
| Answer quality | Score claims and abstention | Answer and source comparisons | 30% | 3/5 | HR | Review incomplete responses |
| Usability | Observe employee tasks | Completion and feedback | 25% | 4/5 | Operations | Improve mobile access |
| Operations and cost | Review support, administration, and pricing | Effort, logs, cost estimate | 15% | 3/5 | IT | Confirm cost assumptions |
The hypothetical weighted result is 72/100. This score is meaningful only because the mandatory gates passed; a permission leak would override it.
Choose go when all requirements and agreed thresholds pass, revise and retest when a fix is feasible, or stop when a failure cannot be acceptably remedied. Record the risk owner, unresolved issues, approved scope, decision date, next review date, and supporting evidence.
How Poppulo Supports Permission-Aware, Sourced Enterprise Search
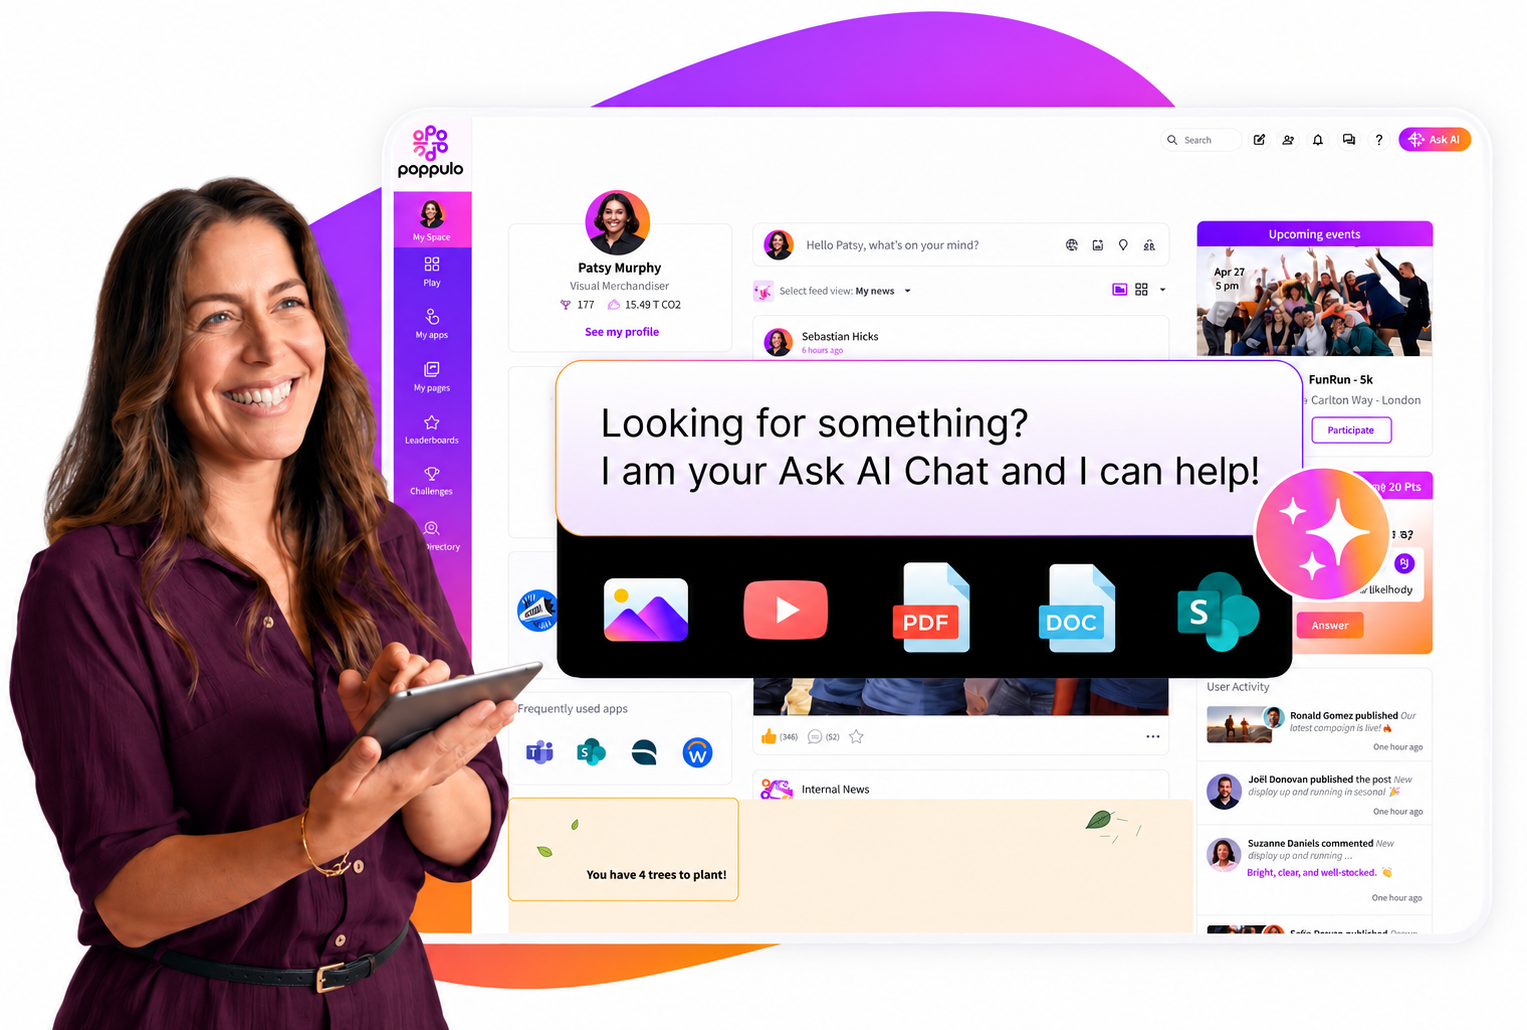
When it comes to platform-based search solutions, the Poppulo Experience Platform empowers users to search platform content and connected sources such as SharePoint. Its Ask AI feature provides sourced answers, while audience permissions and content lifecycle controls support the governance that ultimately determines which key features and internal data employees can access through internal search.
It's easy to put those capabilities through the same pilot as every other shortlisted solution. You can test authorized results and current versions, open source links, search long-form documents and media, and follow the path from an answer to the relevant tool or micro app. Record what happens for your users and content, rather than treating documented capabilities as test results. The results will speak for themselves.
In fact, it was thanks to this effectiveness and ease of use that Poppulo was named a Challenger in the 2026 Gartner Magic Quadrant for Intranet Packaged Solutions and received ClearBox’s Highly Commended distinction.
Final Thoughts
When it comes to your AI checklist, permission safety and reliable evidence are the foundations of trustworthy enterprise AI search. Answer quality determines usefulness once those requirements are met. Start with one high-value task and publish the pilot's owners, rules, findings, and next review date. It's that simple.
At Poppulo, we've worked with global leaders like Accor, Capgemini, Coca-Cola CCEP, EDF, Primark, and TCS to create experience platforms with enterprise AI search, and we'd love to achieve the same results for your company. Ready to learn more?
Book a free personalized demo to discover what the Poppulo Experience Platform can do for your organization.
Enterprise AI Search FAQs
These answers address common questions when evaluating enterprise search software and planning its ongoing performance reviews.
Is Enterprise AI Search the Same as RAG?
No. Enterprise AI search is the broader system for retrieving information across authorized organizational sources. Retrieval-augmented generation (RAG) is one approach for grounding generated answers in retrieved evidence. An enterprise search solution can return ranked documents without generating an answer.
How Long Should an Enterprise AI Search Pilot Run?
Allow enough time to observe content updates, access revocation, realistic peak usage, and at least one remediation and retest cycle. The selected task and its risks should determine the schedule, rather than a universal duration for an elastic enterprise search.
What Is an Acceptable Accuracy Rate for Enterprise AI Search?
No universal threshold fits every use case. Consequential policy or safety decisions warrant stricter requirements than low-risk information lookups. Report missing evidence, unsupported claims, stale sources, and incorrect refusals separately instead of relying on one blended accuracy percentage.
How Often Should Enterprise AI Search Be Re-Evaluated?
Set a regular review schedule with business and risk owners, then add event-driven testing after changes to connectors, models, sources, permissions, policies, or employee audiences. Reuse representative pilot questions to compare results over time and identify emerging risks.